Join the discussion
Write your take first — we'll ask for email only when you're ready to publish.
- Hacker News
- try Manticore Search, it's much more lightweightby leoprctmp
- is there any proof that all these shenanigans impove agent performanceby dominotw
- Cursor and PI harness are the proof.by ozim
- by anthonypasq
- I'm using Typesense to power my take on a md kb, highly recommend this option which positions itself against Elasticsearch and Algolia. Combines vector with bm25 and all the extras you get from a trad search tool like Algolia.by verdverm
- I built one into my agent using sqlite…by reactordev
- At this point building a memory tool for your ai agents is like a right of passage.by marknutter
- Especially for indie users/devs and smaller teams. I built a part of this(the retriever) in < 4 hours https://github.com/itissid/wiki for replacing deepwiki.
I think the challenge is to teach how ranking works to people more effectively so that they can build it for themselves and host them on their own.
Like the other day someone who has worked in search explained to me why you would care about using learning-to-rank(LTR) technique to train your own feature vector weights on your data. My understanding is that weighted features work better(retreival wise) on textual data than plain BM-25 and vector embedding db indexing of text chunks of your data with minimal preprocessing. So if you have lots of conversations you can create a ton of features(like attributes of a conversation) from it and ones that matter more will rank higher. And you can use a regularization(like L1) to kill unimportant ones.
[EDIT]: IIUC, I think LTR is important because you likely want different features to matter more for different parts of your documents, e.g. what matters for codebase documentation is different from your personal journal.
by itissid - I think this is cool and helpful but my biggest complaint is the writing style and word choice just scream LLMby koinedad
- For someone who isn't super familiar, what is "R@10", and is 0.89 good? It's impossible to google forby voidUpdate
- 89% chance the thing you want is among the 10 items returned by the systemby Hexcles
- https://www.evidentlyai.com/ranking-metrics/precision-recall...
"Good" is subjective.
by esafak - Calling this “episodic” memory immediately loses all credibility.
- That’s not episodic memory. It’s a conversation event log with timestamps, decay, provenance, and later consolidation. In cognitive psychology, episodic memory isn’t just “anything that happened and was timestamped.” It’s at least the ability to remember experienced events that occurred at a specific time and place, and here, an event is not a record but any experience (memory).
- I have a request: can this text be even more AI generated?by itissid
- I wonder if one clear sign is so much custom language that makes me wonder "is this lingo used in that field" but more often than not it's just the LLM trying to sound hyper-professional?by Cilvic
- Summary of the article (https://pastebin.com/aawJfrF6) since the original one is like reading an academic paper filtered through an LLM that hates human readers.
It seems like a cool approach. Don't know if it's novel but it's much smarter than "shove markdown files into directories".
by 0xbadcafebee - > but it's much smarter than "shove markdown files into directories".
Is it, though? I mean, is there evidence "bunch of markdown files" is bad while "database the model has to be instructed how to use" is good? `rg` is fast as hell. Markdown is the LLMs native tongue. It does require maintenance of the Markdown files to keep them current, but maybe explicit management is fine. The models can do the grunt work.
BMDF (Bunch of Markdown Files) can be checked into the git repo, they travel to any developer on the project without any setup or special auth, any agent and any model can read them with no special tools to install, and humans can easily poke around and read them, too. And, they can be part of the PR review process, documenting the code and intentions.
I can't come up with good arguments for why a database or search index would be better than documentation in Markddown for any of my projects.
by SwellJoe - TIL
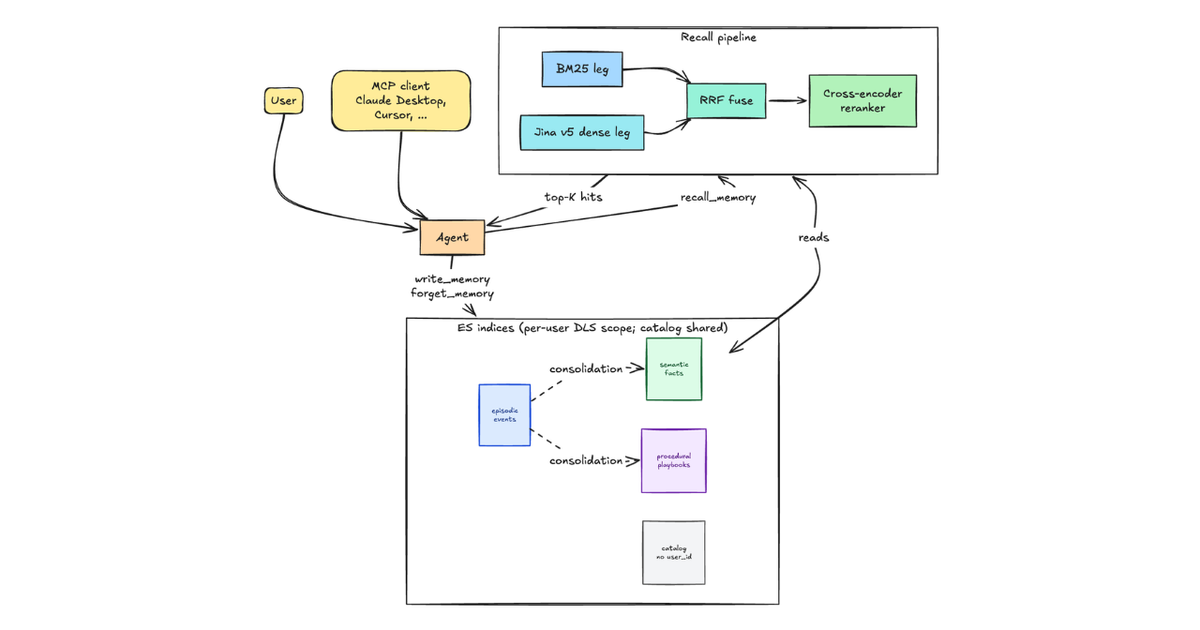
- Hybrid recall + reranker: Two searches merged, then re-scored for best matches
- Supersession: Old facts get hidden, new ones take their place
- Decay: Recent or often‑used memories get a score boost
- DLS: Each user only sees their own documents
by BiraIgnacio - This is such a basic thing nowadays, and ElasticSearch is massive overkill for it. Something like SQLite or LanceDB or basically any vector database is much more appropriate.
This seems to be coming from the “we must make ElasticSearch AI-compatible” department more than anything.
- Would be interesting if one can replace ElasticSearch with something like Typesense hereby xor-eax-edx
- I agree for casual usage, but this seems targeted towards enterprise setups, which makes much more sense to use something like ElasticSearch if you're already in the Amazon cloud, and especially if using the advanced features it provides like they are.by Catloafdev
- Yeah, it's like this Dropbox service they made a big deal about, when one could just make one of its own with rsync and some bash scripting.by coldtea
- The design they talk about includes 3 different types of memory. They store those kinds of memory separately, so that if there's 10 users, all 10 access memories that are more general ("what bulbs work with this kind of light fixture"), and user-specific memories are segregated ("sarah has three lightbulbs"). The different memory types are ranked together leading to a different result. So this is a novel design and use of ElasticSearch-specific featuresby 0xbadcafebee
- ElasticSearch is fine. If your dataset isn't too big you aren't going to hit shard and memory limits and if you do chances are you are already in a large enough organisation that you'll have the manpower to do the required maintenance. It's not rocket science.
> This seems to be coming from the “we must make ElasticSearch AI-compatible” department more than anything.
I don't see the problem in that. It'd be great to have agentic capabilities embedded into Kibana and ES as long as it's not user hostile.
by gchamonlive - Nah, "Any other vector DB" starts to fall apart once you need stuff like scripted scoring like OP uses. Then it starts to be a question of, "do you need ANN for performance?" since SQLite only does brute-force vector scoring. And granted, brute-force is performant for far more vectors than most people give it credit for, but it definitely hits a wall well below 1 million if you want it to have webpage-type latency.
Maintaining Elasticsearch isn't free, but picking an underpowered db and having to port to the right one is also quite time consuming.
by jakevoytko - If you already have Elasticsearch, it makes sense to continue utilizing it.
Saying, “just use SQLite” completely dismisses the idea that this is a _shared_ memory across teams. The ability to easily connect to the remote service and have everything “just work” pays dividends when you have dozens or hundreds of users.
by clintonb