Join the discussion
Write your take first — we'll ask for email only when you're ready to publish.
- Hacker News
- So OpenAI cut Luna's price by 5x, DeepSeek increased price by 5x!
If I'm reading the benchmarks right, they now went from being much cheaper than Luna (but twice as slow), to being roughly same price (but twice as slow).
So all else being equal, where I would previously have used DeepSeek, I can just use Luna, and get the same result twice as fast?
(Yeah I know benchmarks are mostly nonsense, but the ones measuring time are real, and it's the most precious resource.)
by andai - That's a hefty increase. Flash pricing during peak is now 1.32/M out, compared to the current 0.28/M, which in turn is a quite a bit above the cheapest provider at 0.16/M.
https://openrouter.ai/deepseek/deepseek-v4-flash-0731#provid...
by poly2it - Ever since I started using flash, it has slowly crept up to be my default for everything. It is at the good enough state for a fraction of everything else that's out there.
- As well as the headline in/out changes, people heavily using agentic coding tools will want to note the 6x (off peak) and 12x (peak) increase to cache hit pricing on Pro (since cache hit can easily make up 90%+ of input on long sessions).
DeepSeek was hugely underpricing cache hit pricing before and even after this increase they're still cheaper on that metric than every other provider I'm aware of, but it will put an end to those "I used 1 billion tokens and spent $4" reports.
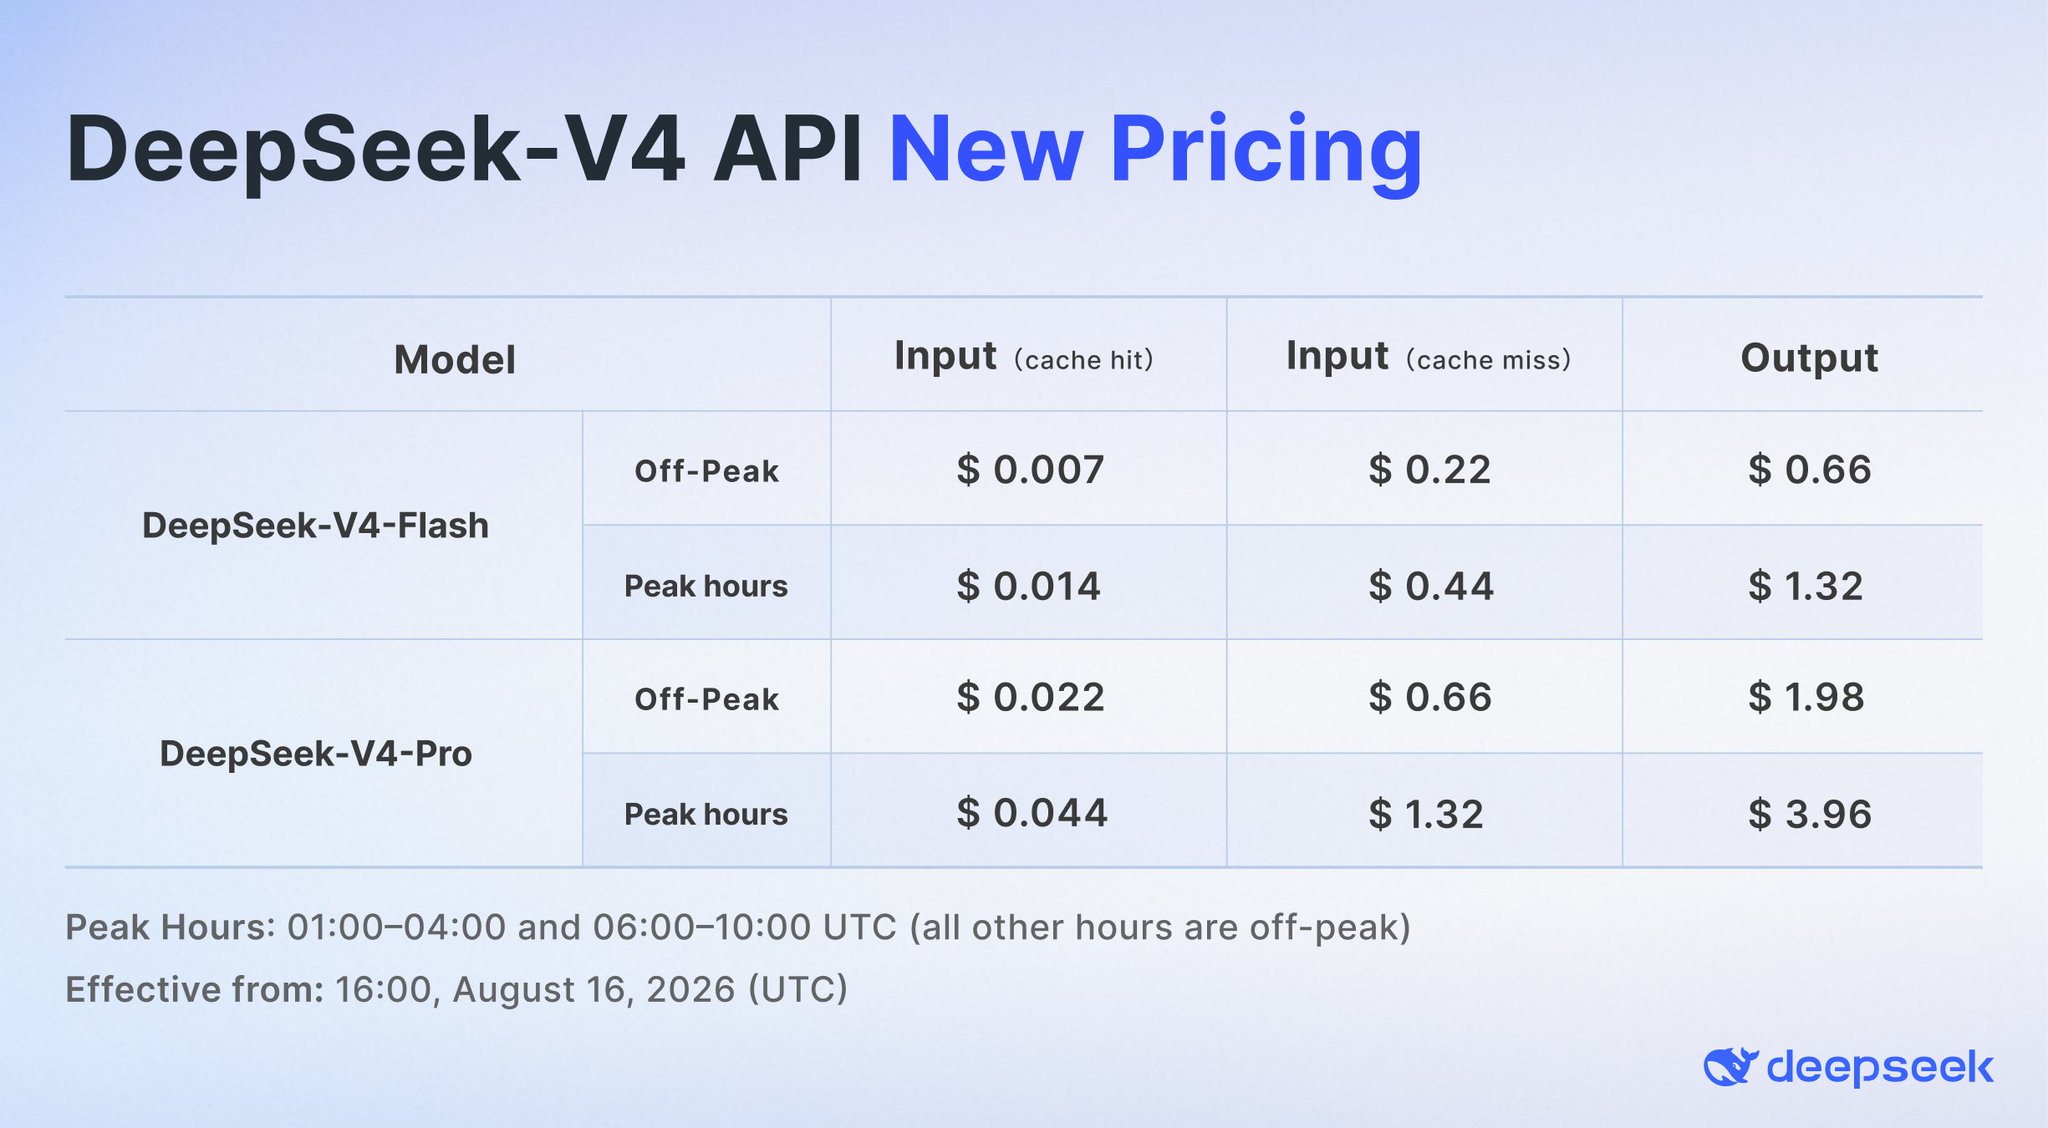
by petercooper - According to their post:
gpt-5.6-luna: $0.20 / $1.20 / $0.02 / $0.25 (In / Out / Cache Read / Cache Write)(Input / Output / Cache Read, [$/M]) DeepSeek-V4-Flash: Prev: 0.14 / 0.28 / 0.0028 Off-Peak: 0.22 (1.6x) / 0.66 (2.4x) / 0.007 (2.5x) Peak: 0.44 (3.1x) / 1.32 (4.7x) / 0.014 (5.0x) DeepSeek-V4-Pro: Prev: 0.435 / 0.87 / 0.003625 Off-Peak: 0.66 (1.5x) / 1.98 (2.3x) / 0.022 (6.1x) Peak: 1.32 (3.0x) / 3.96 (4.6x) / 0.044 (12.1x)EDIT: formatting
EDIT2: giving up on the formatting :-/
by usagisushi - There is no relative/percentage increases noted (understandably). Just because i'm lazy: roughly how much more expensive is it to work with v4 flash and v4 pro through the API, compared to before the price increases? Is it 2x, 5x, 10x higher?by alkonaut
- Old DeepSeek Flash 0731 prices have been independently reproduced.[1] The issue is DeepSeek being inundated and not having capacity to serve the demand, hence the price increases to significantly dampen demand. Never mind international demand either--just think about the magnitude of Chinese domestic demand. Prices for anything related to AI or computing in general (mobile phones, cloud data centre hosting, etc) will continue to climb fast as demand for computer chips _far_ exceeds supply. DeepSeek doesn't have an option other than to just work away on improving their technology in the period of time before computer chips once again become a commodity. For example, DeepSeek's cache ratio for their models apparently leads to 1/2 GPU time requirement versus the second best provider.[2]by dhx
- Interesting to see that peak hours are work hours in China, night in the US and Europe, and also morning in Europe. So Deepseek's customers are mostly domestic.by progval