Join the discussion
Write your take first — we'll ask for email only when you're ready to publish.
- Hacker News
- Pre-AI internet data is like pre-war steel
The slop would multiply if we keep feeding it to new models in a loop
by speedping - I feel like with web search, exa and fetch built into harnesses this is no longer a problem. Haven't faced this issue in months.by datron
- This is one of the things that bothers me about AI.
To me, intelligence or an intelligent entity should be able to learn from its mistakes and learn new things on its own. Having to start from scratch to teach an AI new facts or new skills is not very intelligent IMO.
by SirMaster - Do people prefer the new flat style LLMs are producing? I don’t mind it as much as the gradient theme they were pumping out previously.by ryanschaefer
- For general purpose use this is interesting, but if I'm just using an LLM for coding, does this matter at all? I would hope something like a new java version after a model's publish date can be handled and understood by the model through tool calls and context even if it's not explicitly in the training data, the same way the LLM doesn't have my existing code or the plan to change it baked in from training.by ctkhn
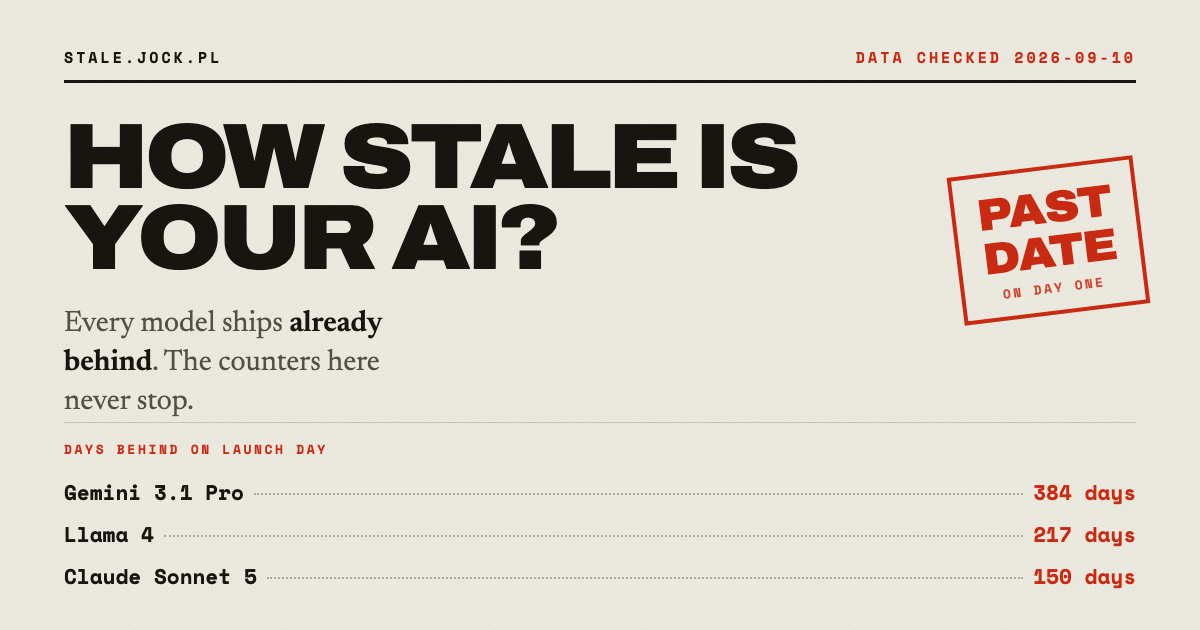
- This is why I am not worried about AI taking over the world. Every thread is frozen in time. Interesting that Astra has 2 months earlier cutoff than Fable 5.1.. Does that indicate much bigger (and therefore longer) training run?by BraamV
- It still matters, but in the age of good reasoning, tool use, and web search, this is much less of a problem than it used to be.by jasonjmcghee
- I remember when the US captured Venezuelan president Maduro, and when I posed a prompt related to this, the model said that’s pure fiction. I told it to double check. Still didn’t want to entertain the idea. It only acquiesced when I specifically directed it to check Reuters. I haven’t noticed this problem in months. Model cutoff seems to be less of a problem these days.by gjskngnf