Join the discussion
Write your take first — we'll ask for email only when you're ready to publish.
- Hacker News
- Yeah the calibration is really what makes it useful in practice for quick, small decisions. Asking a LLM to give scores to a problem will yield inconsistently scaled/anchored results that changes at a whim.
The blog is pretty heavy on statistics. I'll have to study it more when I have time. Is it essentially bootstrapping results to statistically normalize the answers?
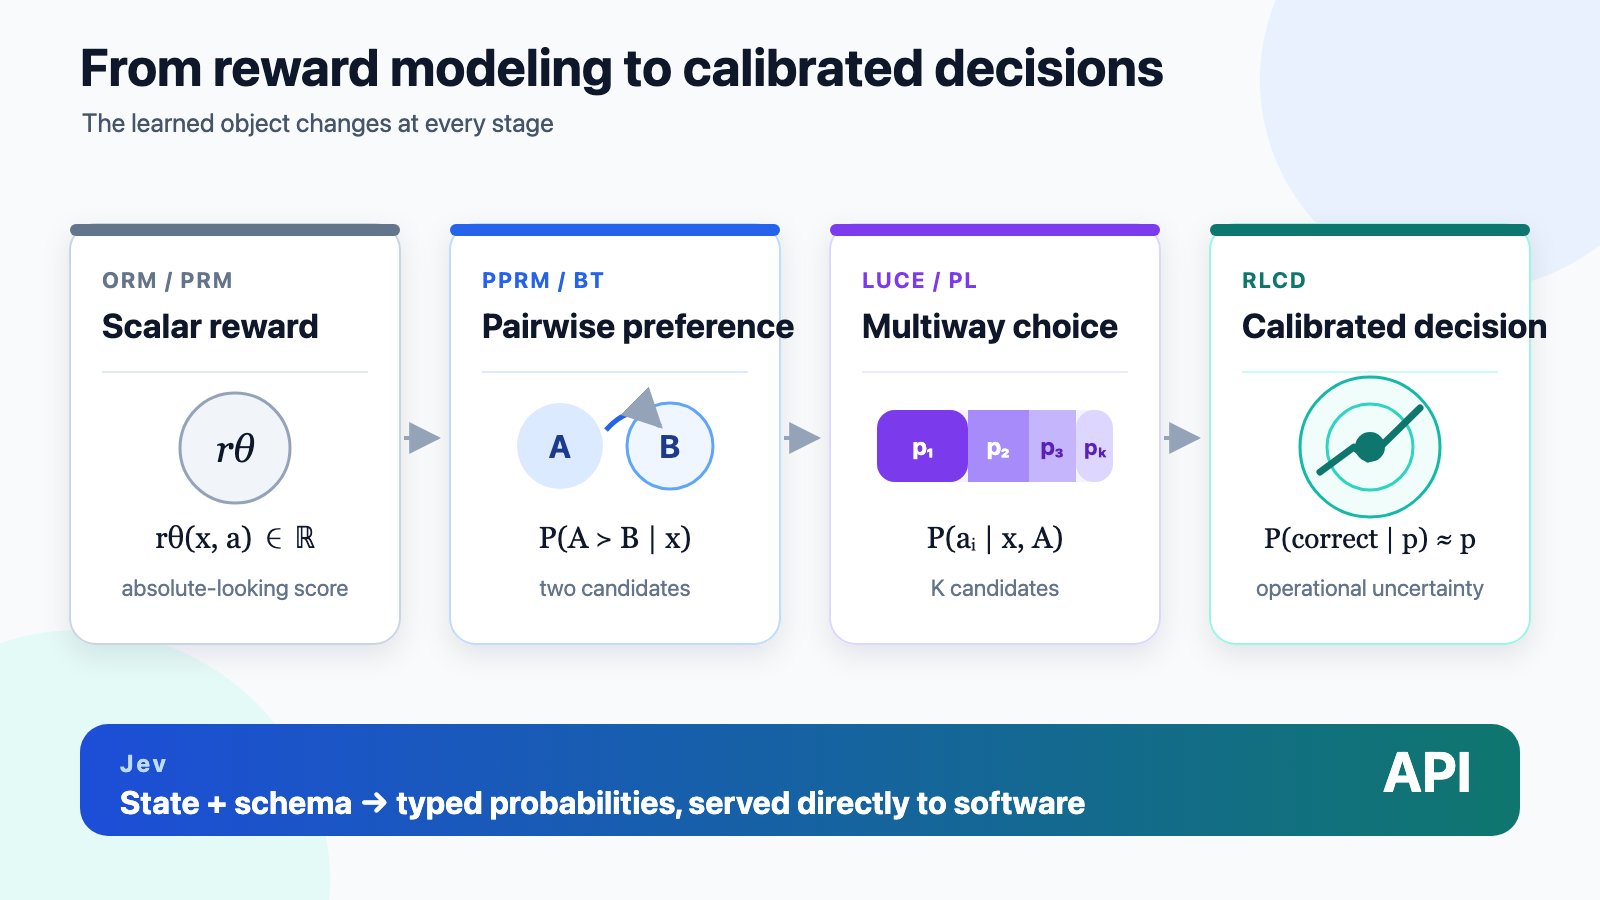
by daemonk - RLCD, not defined in the article, is Reinforcement Learning for Calibrated Decisions.by WalterGR
- > The operational signal was always relative preference. The scalar merely hid it.
Is this another Claude-ism? "X was always Y. The Z merely hid it." Or am I overcalling it?
by firejake308