Join the discussion
Write your take first — we'll ask for email only when you're ready to publish.
- Hacker News
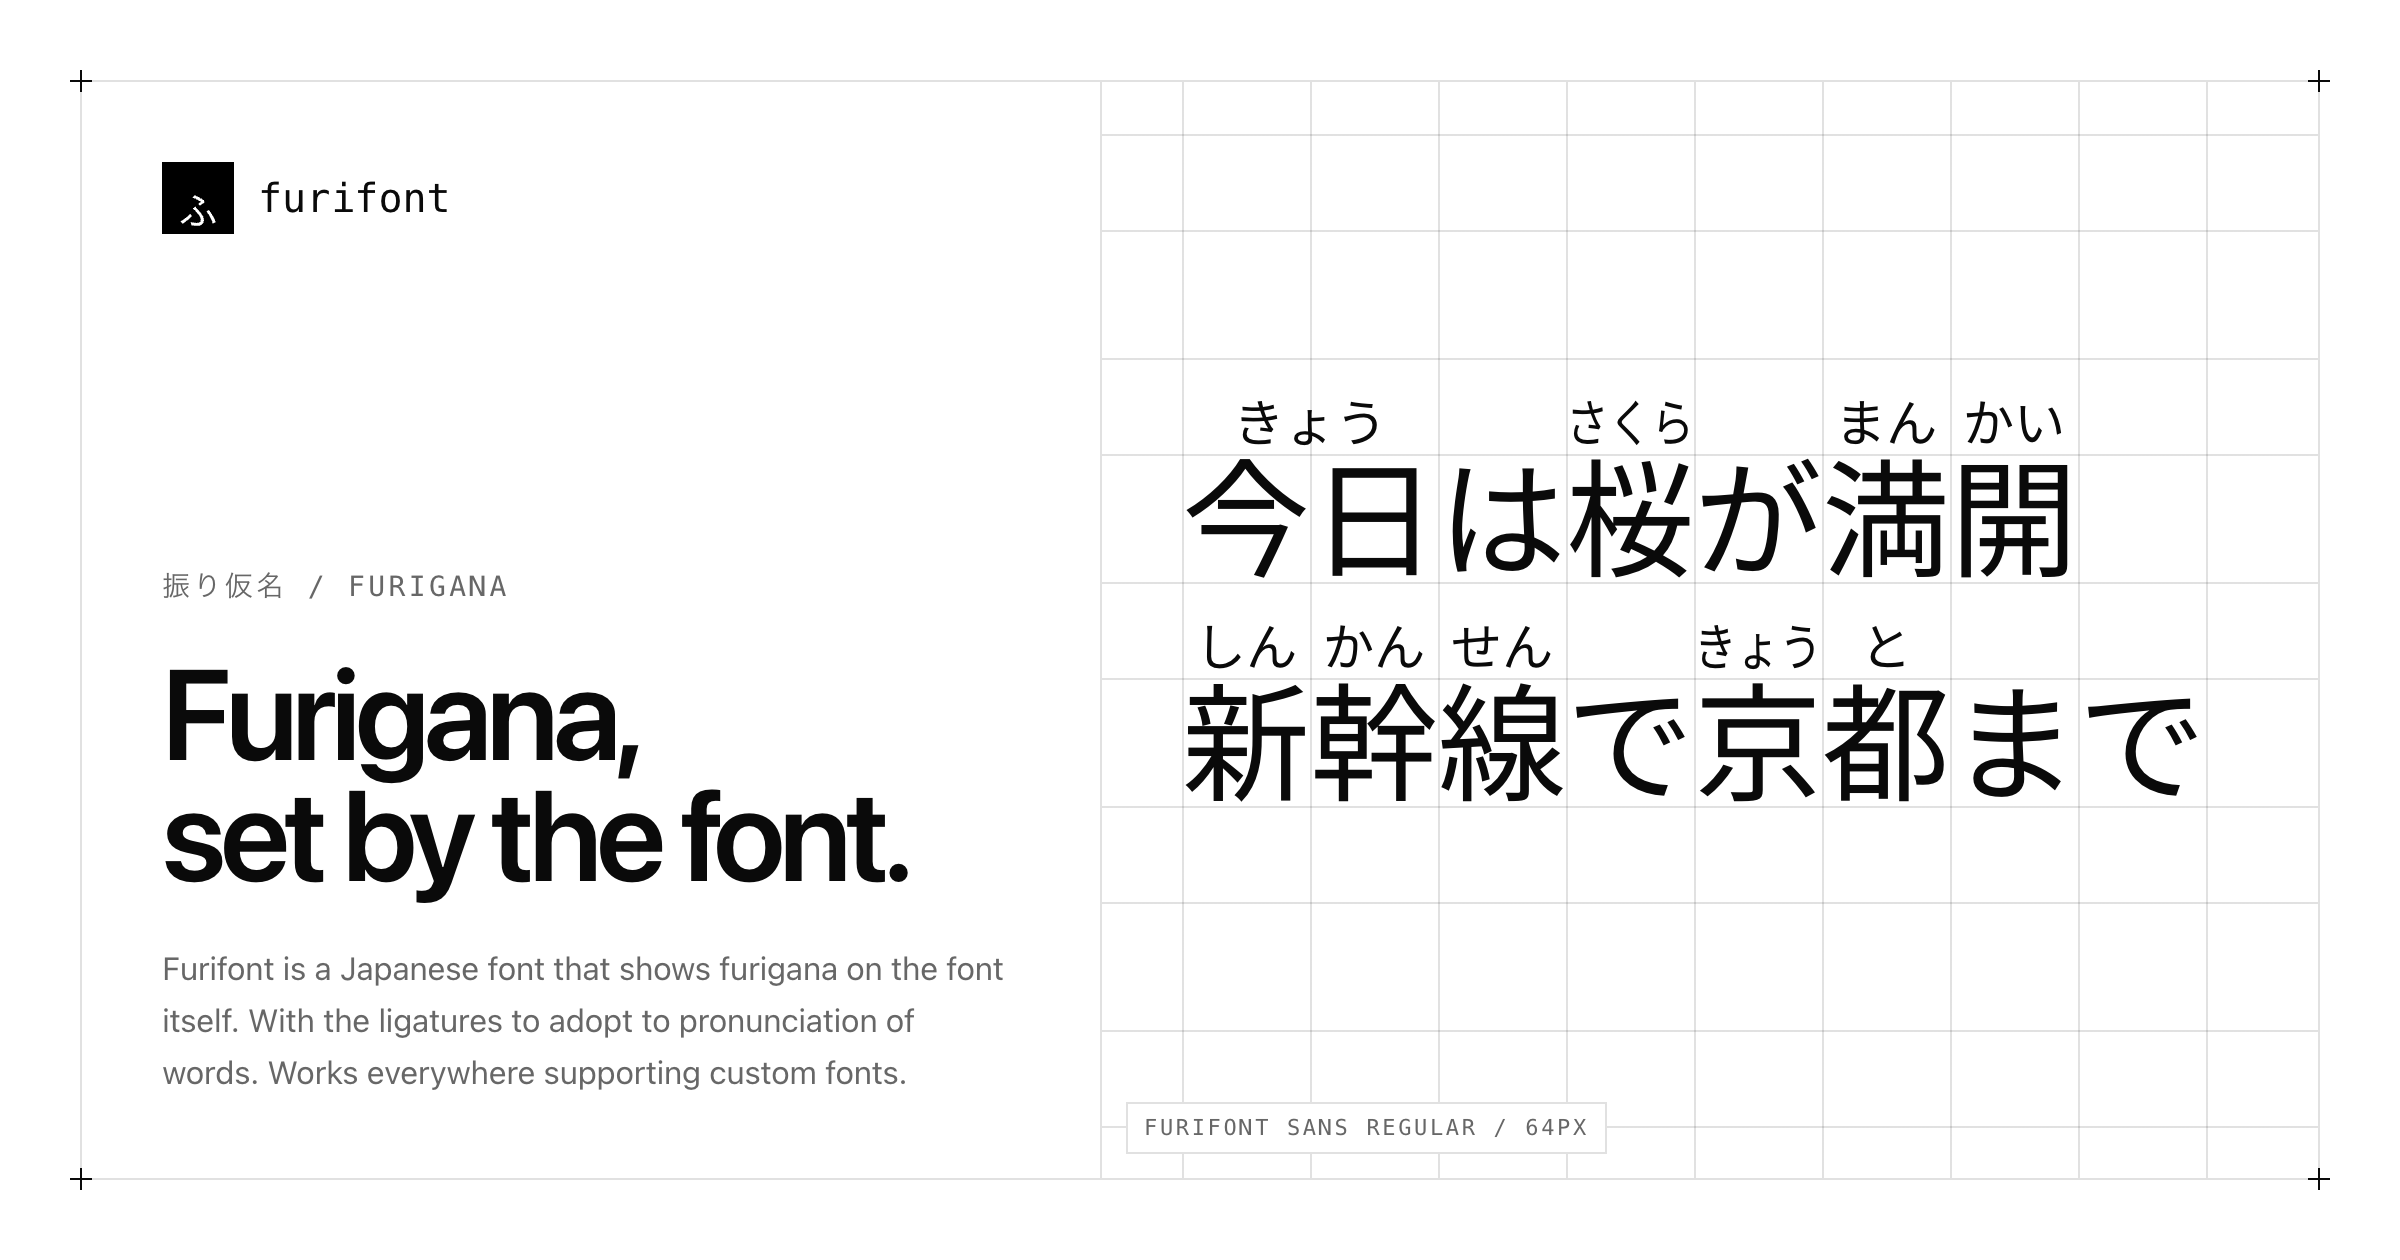
- This is an interesting use of ligatures for sure. However, I really don't know when one would use it. Couldn't you just use Ruby tags for a website?by jbm
- This is really nice. I'm able to read Hiragana and Katakana fully after about 4-6 weeks now but then I'm hit with the reality of how many Kanji I have to learn still everytime I want to read something in real life lolby alasano
- This is very cool. Unfortunate that it gives the wrong pronunciation when words get split in a line wrap (e.g., 大学 got split between lines and changed to incorrect furigana for me).by jwolfe
- 01, 02, 03, 04
never even gets to 10!
by randyrand - I like how for この先生きのこるには, it has この先生(せんせい) as opposed この先(さき)生(い)きのこる. Maybe it's learning from memes.
https://dic.pixiv.net/a/%E3%81%93%E3%81%AE%E5%85%88%E7%94%9F...
by omoikane - Automatic furigana is not really possible to be reliable considering readings heavily rely on context that can't be easily inferred, but I'm sure it will help some people who can't read very well.by teshigahara
- Really nice font! Native Japanese speaker here, and seeing furigana done purely in the font is very cool.
One small thing on the Japanese version of the page: in the "Ligatures do the work" section, 合字 itself only gets じ over 字, and 合 has no reading. It should be ごうじ. I guess 合字 isn't in the dictionary, so it falls back to single kanji, and 合 is skipped because it has several readings.
by shun_dev - I think this is a rare “useful” abuse of font ligatures, and in that respect I think this is a cool project, but it's also a terrible idea that nobody should actually use, because Japanese kanji readings are famously ambiguous and context-dependent. The modal character has two different readings without counting those used in personal names, nor contextual slight changes to pronunciation. Some characters have six different readings, and that's again without counting those used in personal names. There's no way a font can do a good job at it unless you can somehow stuff an entire LLM in there.
For context, it's a hard enough problem that Google Translate's own romanised pronunciation guides are frequently wrong, or disagree with their text-to-speech.