Join the discussion
Write your take first — we'll ask for email only when you're ready to publish.
- Hacker News
- Do this exercise: Take your company's market cap and divide it by the total number of lines of code in the company's repo. You'll discover that don't need that much code to create value. For Google (somewhat publicly somewhat known), this is something like $2000 per line of code. Your company is probably not too different, certainly within an order of magnitude.
So let's assume 1 line of correct code is approximately 10 tokens and $1000 of value. If you could theoretically write the correct code, $10 per 1M output tokens should get you $100K worth of value, or 10000x return! Obviously, thought experiment, very theoretical limit no one can achieve, doesn't include thinking tokens, etc, but it's worth thinking about how much your code is actually moving the needle.
Maybe I'm doing things wrong, but I don't need that much code and I don't spend that much time producing code (maybe 1000 lines in a productive day), because the bulk of my time is spent researching, testing, evaluating, thinking, etc to find out how to write only very valuable code. 1000 lines is laughable compared to what tokenmaxxers do, but over the course of a month that's a 200-300K codebase and anyone who has worked on something of that size knows it can support a sizeable business.
- Why is this on the front page? The article doesn't really have any new insightsby parthdesai
- Increased code changes should be seen as a bad thing. It's funny that their response is "let's invent a git alternative"
If a module lifespan before it's replaced/refactored is less than a week, then it wasn't a good module to begin with.
This is just hiding all the spaghetti mees that they must have in the back
by gonzalohm - I'm curious how this will play out.
Perhaps their latest models have ushered in an era of exponentially increasing productivity.
Perhaps they've lost control of their process.
If they've lost control, the system will reach an ugly complexity steady-state of sorts, where any change to improve things will, on average, result the same amount of regression. You'd have to hope the next, new, more capable model would be able wind things back (and not just let you raise the level of complexity, which really just leaves you in an even deeper mess.
To my mind, taming exponential phenomena is hard to do, and requires very careful planning and preparation. I don't see evidence of that here. So my bet is this is an out-of-control mess.
But it will be interesting to find out. (And I think we will find out -- I think it's already too big that they could hide it if it's blowing up or collapses.)
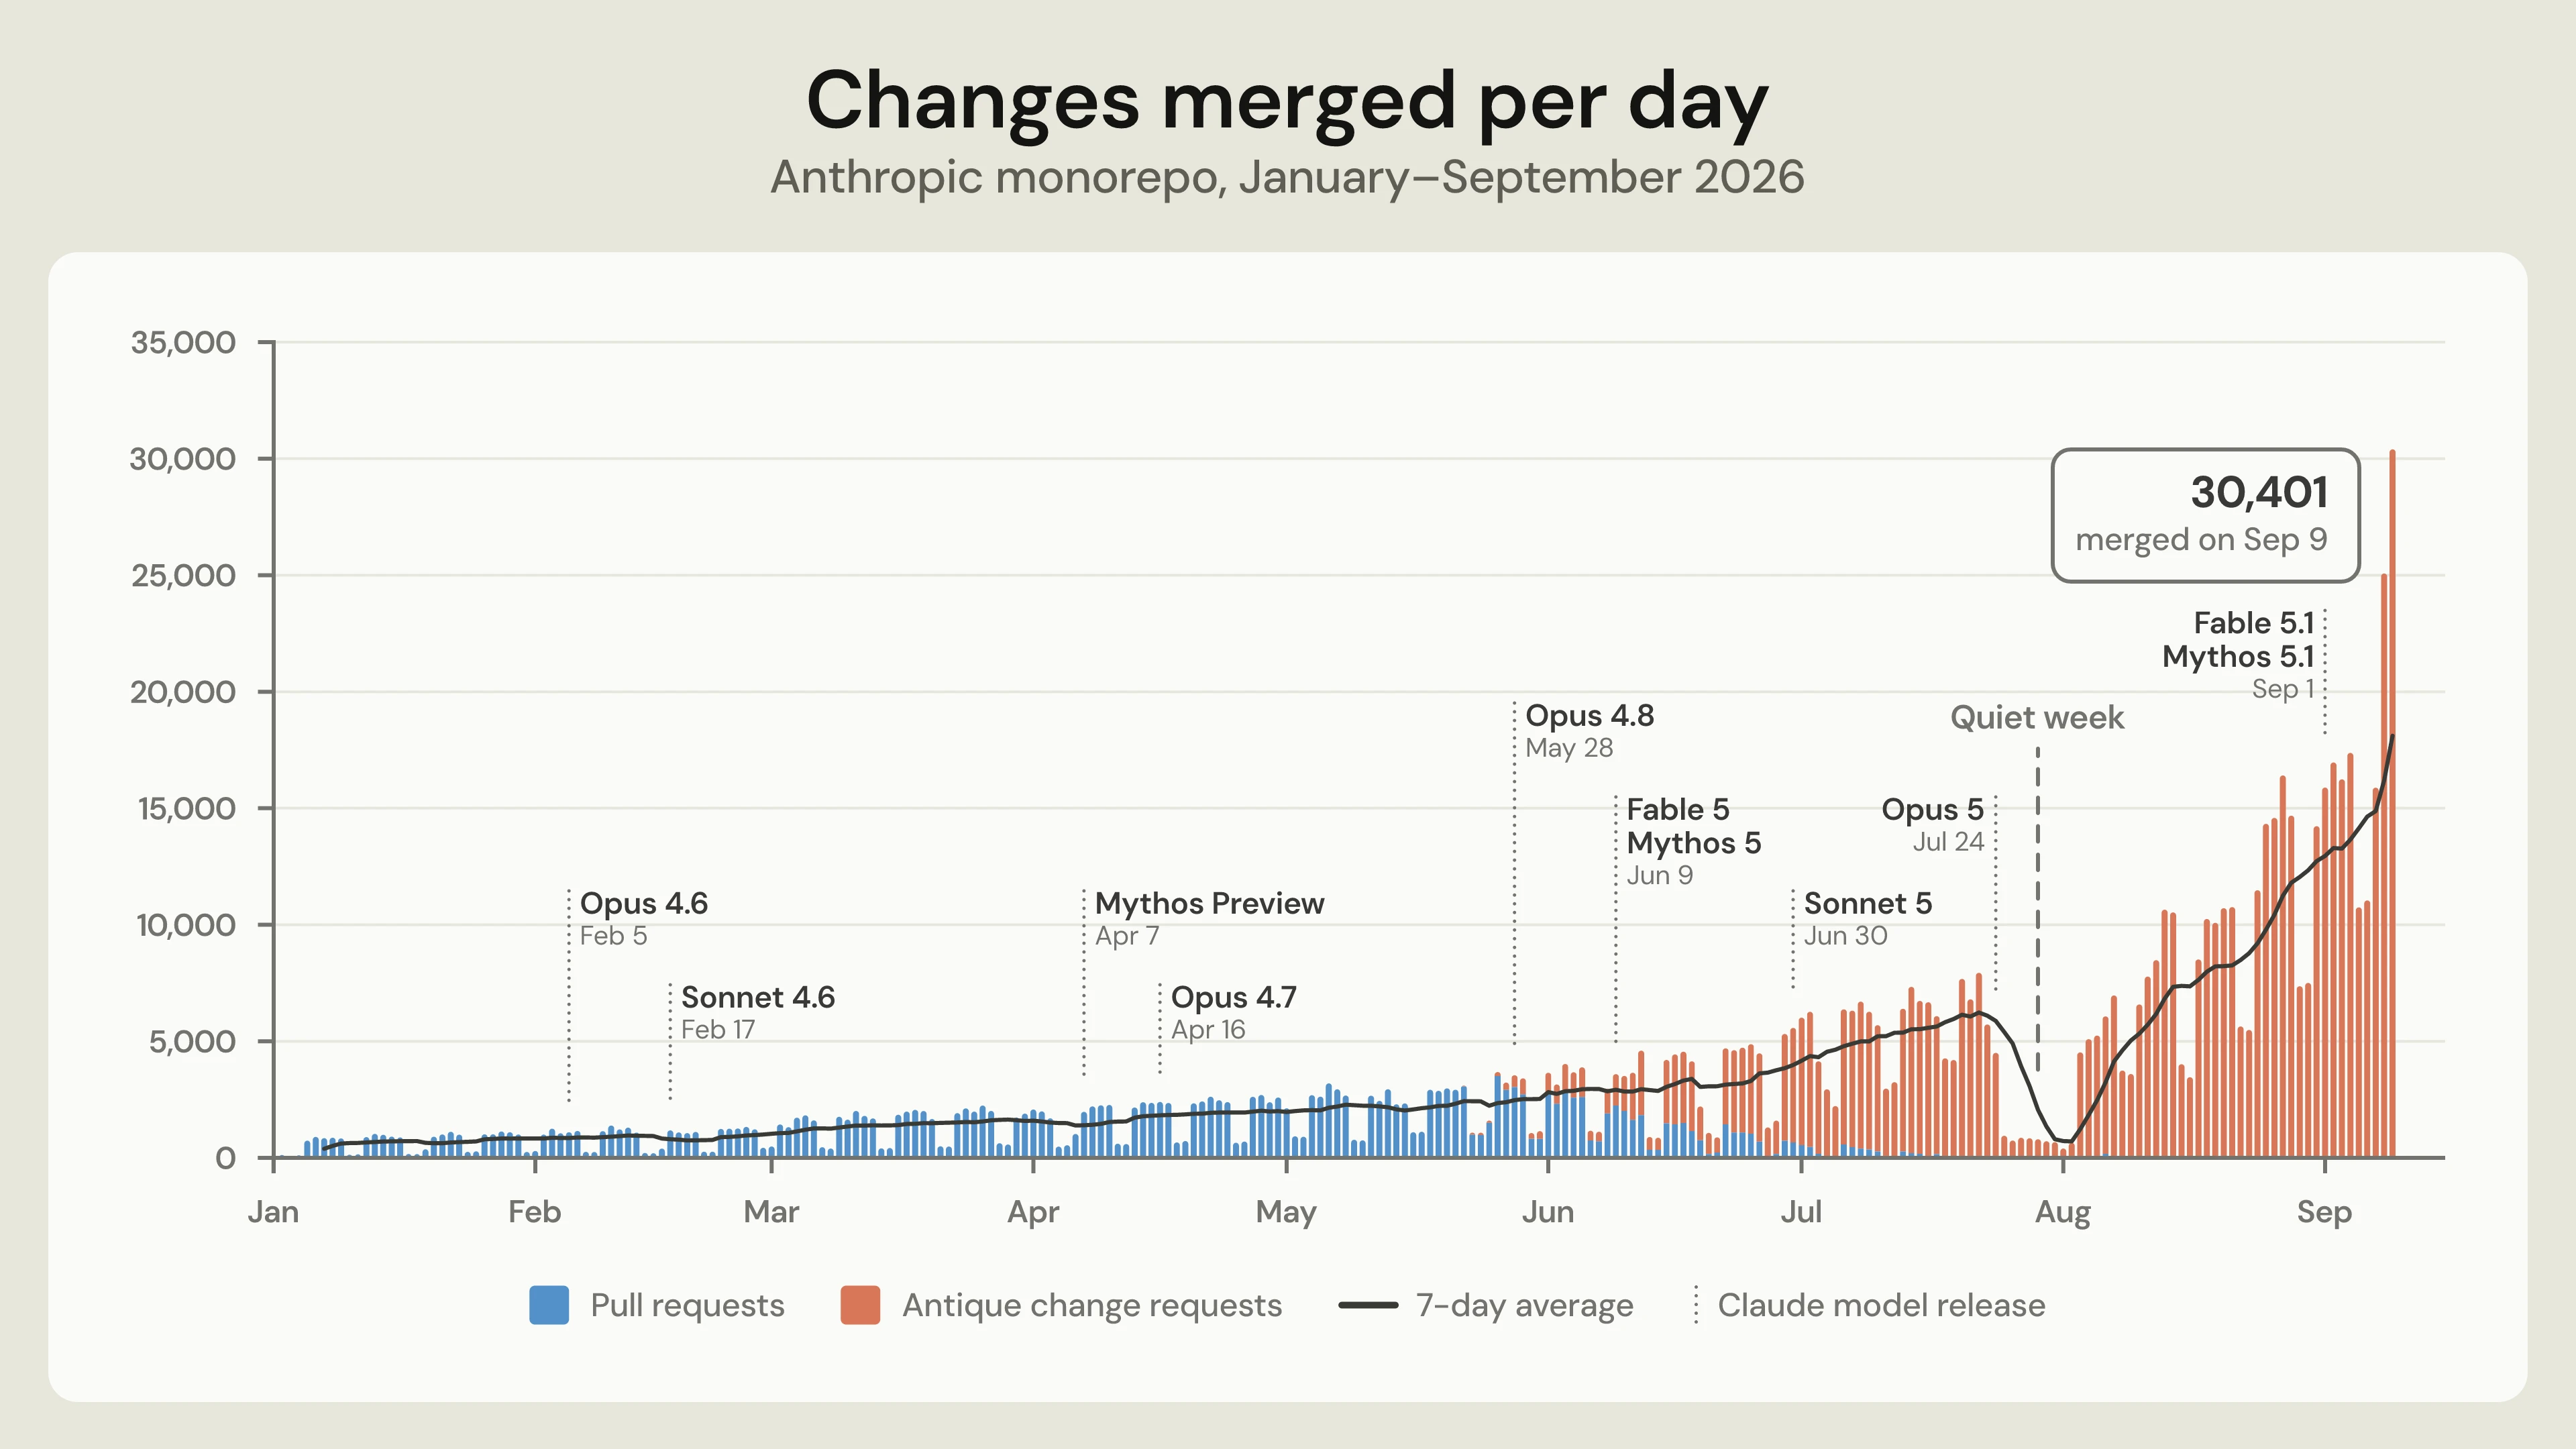
by jmull - Does the output of Anthropic _feel_ like a company merging 30,000 commits per day?by rogerrogerr
- It's almost impossible to avoid over-engineering these days. I can't make other people generate minimalist code. Before AI, you could reach alignment with your team members and produce high quality, minimal code, but nowadays I find it impossible because:
- People believe they will be able to maintain code just as easily as they can generate it and it's hard to explain the asymmetry to people who haven't experienced it themselves.
- People don't feel like coding is a craft anymore so they don't care about how the code looks. They just want it to appear like it's working and don't care about anything else. As a team leader, you can't get people to overcome this deep sense of apathy they feel towards the code.
by jongjong - I'm more curious about Antique. Code review is my bottleneck, this meatbag here can't keep up with the agents at all. I either spend too much time and energy on trying to understand the code (not just in terms of review, but to maintain my mental model of the codebase), or just give up and hope for the best.
The over-engineering is definitely a concern too. It's not that how Fable/Opus architect code is bad, far from it, but the projects I'm working with are not always at a scale where it matters as much, and simpler more readable abstractions might be a better trade-off.
by Anonyneko - > steer Claude away from over-engineering parts of the system in response to hypothetical concerns.
This is my biggest problem with opus 5.5.
It's absolutely incredible in many ways, but it has no sense of "good enough".
It will go around in circles polishing something so to resolve edge-cases on edge-cases.
"Someone could create a class that calls your public method in such a way, that under 3 other race-condition properties, there might be stale data read".
It has no sense that it isn't appropriate to add a half dozen classes just to close that kind of hole, especially when there isn't even such a caller or possible conditions at present.
by xnorswap